PostgreSQL 18: five changes worth testing on your database
PostgreSQL 18 adds async I/O, B-tree skip scan, uuidv7(), OAuth, and new generated columns. Where they help, what they do not promise, and how to prepare a safe migration.
The release changes several parts of the database engine itself
PostgreSQL 18 was released on September 25, 2025. Its release notes cover several independent directions: asynchronous I/O for selected read and vacuum operations, B-tree skip scan, timestamp-ordered uuidv7(), virtual generated columns, OAuth support, and temporal constraints. [1] This is not one large feature to enable with a checkbox. It is a set of capabilities that each need to be compared with a schema, query plans, and operating environment.
The worst way to assess the upgrade is to say ‘Postgres 18 is three times faster’. The PostgreSQL Project reports up to 3× improvements in certain storage-read scenarios, but that result belongs to specific I/O conditions. [2] A query bound by CPU, locking, network latency, a poor index, or a slow upstream service will not change automatically.
A better reason to upgrade is a specific pain the release may address: large scans and vacuum work, random UUID primary keys on a table with active inserts, queries filtering a non-leading column of a multicolumn B-tree, or a need to connect clients through a corporate OAuth flow.
What to test before migrating
Every capability below has a clear test. If you do not have that test, it should not be the main reason for an upgrade.
| Capability | Where it may help | What to test |
|---|---|---|
| Async I/O | Sequential scans, bitmap heap scans, vacuum, and other supported I/O operations. | Compare EXPLAIN (ANALYZE, BUFFERS) and wall time on staging with production-like data; inspect storage and the io_method setting separately. |
| B-tree skip scan | Queries skip one or more prefix columns of a multicolumn B-tree but filter later columns. | Capture plans before and after. Check whether an existing index is now used before adding another index on speculation. |
uuidv7() | New tables or append-heavy writes that require UUIDs and creation-time ordering. | Measure inserts, index size, and range queries on a new table. Do not rewrite historic primary keys without an independent business reason. |
| Virtual generated columns | Derived fields that are read more often than modified, or where storing a duplicate would be undesirable. | Compare read-time computation with the current stored approach and check the effect on queries and indexes. |
| OAuth | Client connections that need SSO or a device-authorization flow. | Test driver support, the identity provider, scopes, token refresh, and emergency administrative access. |
`uuidv7()` reduces randomness in new keys; it does not eliminate index design
UUIDv4 is useful as a distributed identifier, but its random order spreads new entries throughout a B-tree. uuidv7() includes a time component, so new values mostly move in one direction. PostgreSQL 18 ships the function in core. [1] For new external identifiers, it is often a better default than an application-generated UUIDv7 or a separate extension.
‘Mostly’ matters here. UUIDv7 does not guarantee absolute order across every concurrent write, solve contention on a hot index, or replace sensible partitioning. It gives a key whose time order aligns better with insertion order. Look for the gain in the actual write-path metrics, not in the appearance of the ID.
For an established system, the calmer approach is often hybrid: historic UUIDs remain while new tables or entities use UUIDv7. Replacing a primary key at scale touches foreign keys, caches, API contracts, replication, and backup processes. A database release alone is not a reason to take that risk.
A safe upgrade starts with restoration, not a production command
PostgreSQL lists three main paths between major versions: dump/restore, pg_upgrade, or logical replication. [1] The choice depends on acceptable downtime, data size, and rollback requirements.
Capture a baseline
Save top queries, EXPLAIN (ANALYZE, BUFFERS), latency, autovacuum behavior, and table and index sizes. Without a baseline, a regression cannot be separated from ordinary workload variation.
Restore production-like staging
Test more than schema migration: extensions, roles, jobs, backup and restore, drivers, and integrations. After pg_upgrade, check separately that statistics and plans behave as expected.
Run critical workload
Test read and write paths, batch jobs, maintenance windows, and degraded cases. I/O changes depend on your storage, so a synthetic benchmark without similar data says little.
Make rollback a technical plan
Define a stopping point, integrity checks, decision ownership, and the route back. If short downtime is required, evaluate logical replication and rehearse the cutover.
OAuth complements, rather than replaces, access hygiene
PostgreSQL 18 adds OAuth support, and libpq implements an optional Device Authorization client flow. [3] That is useful where database access needs corporate identity, scopes, and short-lived tokens. Not every driver or connection path will support it at once, so a compatibility test is required.
The release also continues the move away from md5 password authentication; MD5 support is planned for removal in a future major release. [1] This is a useful time to check whether every client supports SCRAM, where credentials live, how access rotates, and which service accounts still bypass ordinary rules.
The upgrade should end in a measured decision
PostgreSQL 18 gives enough reasons to place an upgrade on a roadmap. The strongest reason will differ by system: I/O and maintenance in one, UUIDv7 for new write-heavy tables in another, multicolumn indexes elsewhere, and OAuth in another. None of these removes the need for staging and a baseline.
After a pilot, the result should be specific: upgrade because critical scans became cheaper; use UUIDv7 only for new tables; keep the current indexes; defer OAuth until clients are ready. That decision list is more useful than a broad claim that a new version is ‘faster’.
Official sources
Related Articles
How to Add Mau Saver to a Telegram Group and Save Media in Chat
A practical guide to adding Mau Saver to a Telegram group and downloading videos, audio, and posts directly in the chat.
How to Advertise to an International Telegram Media Audience
A practical guide for advertisers: reach an international Telegram audience through Mau Saver Bot, group placements, pinned posts, and native media integrations.
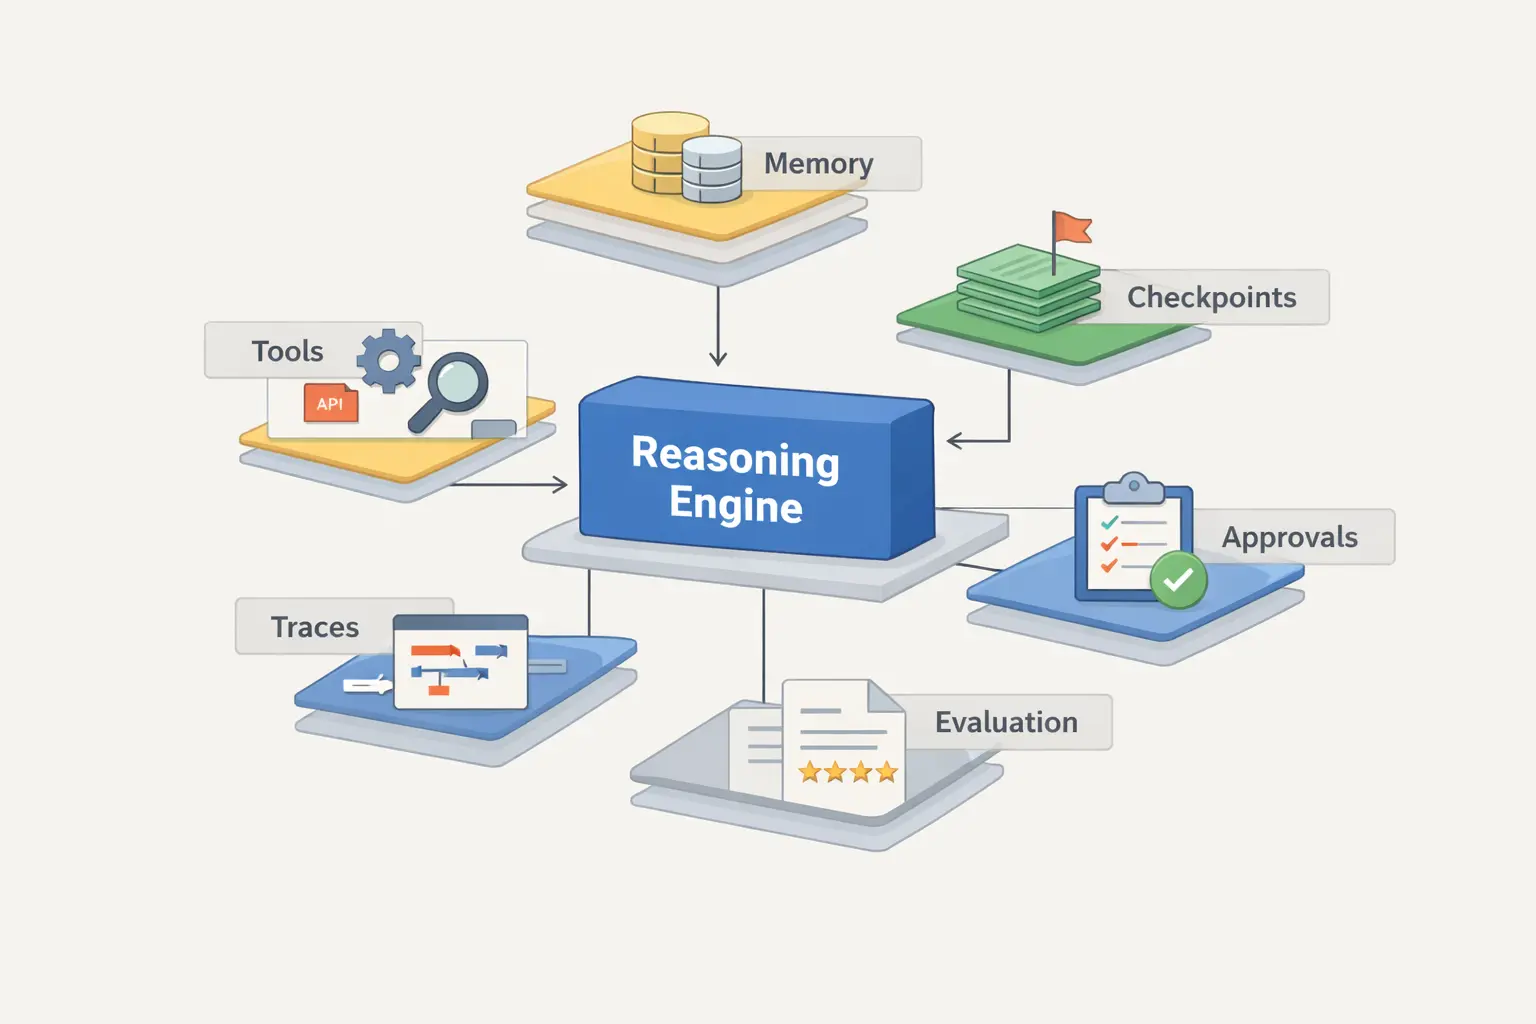
AI Assistant Development Cost in 2026: RAG Chatbots, CRM Integrations, Guardrails, and Support
A practical buyer guide to AI assistant development cost in 2026: prototypes, RAG chatbots, knowledge-base assistants, CRM and website integrations, guardrails, evaluations, monitoring, and support.
AI Can Make More. Not Better: What Game Development Research Actually Says
Generative AI is entering game production, but the evidence is more nuanced than the hype. We examine developer adoption, player reception, quality risks, and a practical production model for using AI without outsourcing taste.